
Most tutorials on how to create SQL views tell you to wrap any SELECT in CREATE VIEW, call it reusable, and move on. That advice is wrong in the two places that matter in production. A view doesn't make a slow query fast, and a WHERE clause inside a view doesn't make sensitive data secure.
Treat a view as a named contract instead. You're publishing a grain, a column list, and a freshness promise that reports, pipelines, and applications will depend on. If you materialize that contract, you're also publishing a storage and refresh lifecycle. I would start with the simplest standard view that meets the contract, then earn the right to index or materialize it with measurements and permission tests.
Table of Contents
- Pick a Standard, Indexed, or Materialized View
- How to Create SQL Views Step by Step
- Test What the View Actually Hides
- Measure Read Gains Against Write Cost
- Fix the Errors That Block the View
- Version the View and Decide the Next Step
Pick a Standard, Indexed, or Materialized View
Pick the storage model before you write a line of SQL. That choice decides whether readers see current data, whether writers pay maintenance on every change, and whether someone has to monitor lag at 2 a.m.
A standard view stores only the query definition. The database runs that SELECT against the base tables on every read, so results stay current and there's nothing extra to refresh. Use it to hide sensitive columns, stabilize names that differ across source systems, or give every consumer the same customer or order shape. It's the right default when freshness and one shared definition matter more than saving repeated join work.
When stored results earn their keep
A SQL Server indexed view stores result rows in a table-like form. You don't get that storage by accident. The view needs SCHEMABINDING, and the first index must be a unique clustered index. Only after that index exists can you add nonclustered indexes. In exchange, every write to a referenced table has to maintain those stored rows.
A materialized view makes a different trade. It stores the result and refreshes it on a schedule, so readers accept a known lag. Snowflake exposes a refresh timestamp and a BEHIND_BY measure for that lag, PostgreSQL fills rows at creation and updates them with REFRESH MATERIALIZED VIEW, and Databricks views stay logical unless you create a materialized view with a refresh schedule. If you can't name the refresh owner, frequency, lag limit, storage cost, and statistics upkeep, you don't have a materialized view design yet. You have a hope.
Practical rule: Materialize only when the same expensive join or aggregation is read often, controlled staleness is acceptable, and you can monitor the lag you promised.
Portability should shape the choice too. In 2024, 79% of organizations reported using two or more database platforms, up from 62% in 2020, according to Redgate's State of the Database Landscape report. Keep SELECT, JOIN, WHERE, and GROUP BY portable across SQL Server, Azure SQL, and Databricks, and isolate engine extras like binding clauses and refresh syntax in separate scripts. That separation is what makes a shared definition workable in a unified data modeling approach rather than a set of lookalike views that drift.
Which SQL view to create
| View type | What is stored | Freshness | Create it when | Engine note |
|---|---|---|---|---|
| Standard view | Query definition only | Always current with base tables | Hiding columns, stable names, or a shared business grain | CREATE VIEW in SQL Server, Azure SQL, and Databricks |
| Indexed view | Result rows, maintained on DML | Current, at a write cost | Repeated joins or aggregates on SQL Server after a measured bottleneck | SCHEMABINDING plus a unique clustered index first |
| Materialized view | Stored result refreshed on a schedule | Stale by a known lag | Expensive reads where delayed data is acceptable | Snowflake BEHIND_BY; PostgreSQL REFRESH MATERIALIZED VIEW; Databricks SQL refresh |
Lock one row of that table before you code. If the business needs live order status, a scheduled materialized view is the wrong answer no matter how fast it reads. If a dashboard refreshes hourly anyway, paying write maintenance for an indexed view may be waste you can measure and remove.
How to Create SQL Views Step by Step
Use one worked example throughout, dbo.vw_OpenOrders, with one row per open order. That grain statement sounds trivial. It's the thing that catches fan-out, duplicate keys, and inflated totals before a report ships.
The flow below shows the sequence from contract to tested output.
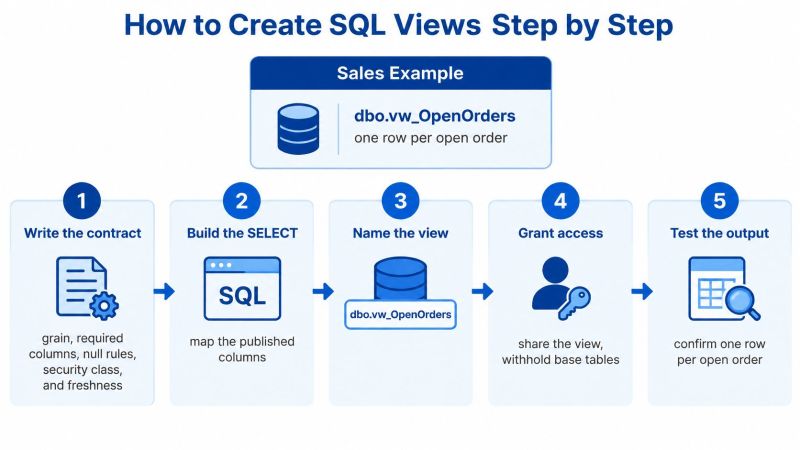
The six steps
Write the contract first. Record the grain, required columns, null rules, security class, and freshness expectation. For a standard view, freshness is live. For open orders, decide what open means, whether a missing shipment date renders as NULL or excludes the row, and who may see customer identifiers. This step prevents the classic argument where finance and operations both claim the view is wrong because they meant different things by open.
Draft a deterministic SELECT. Use explicit column names, stable aliases, and fully qualified objects, never **SELECT ***. Qualify every column after a join so an added source column can't create ambiguity later. **SELECT *** breaks reports when a new column appears, because positional consumers shift without notice. This discipline matches the repeatable method in Microsoft's indexed views documentation, which also stresses validation and execution plan review before deployment.
Create the view with the platform statement. In SQL Server or Azure SQL, use CREATE OR ALTER VIEW dbo.vw_OpenOrders AS followed by your SELECT. In Databricks, use CREATE OR REPLACE VIEW catalog.schema.vw_open_orders AS followed by the same portable SELECT. Keep the business logic identical and let only the wrapper change.
Reconcile against a trusted source query. Compare row counts, duplicate keys, join cardinality, null rates, and one known total. An untested many-to-many join inflates totals while still looking plausible row by row. Check for duplicate order keys directly, because that single test exposes most fan-out.
Read the execution plan. A standard view stores no rows, so speed depends on the optimizer and indexes on the base tables. Confirm the plan uses sensible joins and seeks where you expect them. Don't index the view to fix a missing base table index you haven't looked for yet.
Commit the script as an API. Put owner, grain, and consumers in a header comment, and deploy through version control with dependency checks. Keep SCHEMABINDING, NOEXPAND, and Databricks refresh clauses in a separate script so the business SELECT can move across SAP, Azure, Fabric, and Databricks estates without carrying one engine's rules into another.
CREATE VIEW syntax by platform
| Platform | Create statement | Notes |
|---|---|---|
| SQL Server | CREATE OR ALTER VIEW dbo.vw_OpenOrders AS followed by the SELECT | Use schema-qualified names and no SELECT * |
| Azure SQL | CREATE OR ALTER VIEW dbo.vw_OpenOrders AS followed by the SELECT | Same syntax as SQL Server; check indexed-view rules before adding SCHEMABINDING |
| Databricks | CREATE OR REPLACE VIEW catalog.schema.vw_open_orders AS followed by the SELECT | Logical view; use CREATE MATERIALIZED VIEW with a refresh schedule only when lag is acceptable |
Treat the view as an API, not a saved query. If you wouldn't change an API response shape without telling consumers, don't change a view's columns or grain without telling them either.
You're done when a report or pipeline account can read dbo.vw_OpenOrders, get exactly one row per open order, and reconcile to the trusted total. Anything less is a draft with a production name.
Test What the View Actually Hides
A filtered view creates false confidence faster than almost any other database object. You removed the salary column, added a region filter, and granted access to the BI team. That feels like security. It may only be presentation.
The image below frames the gap between what a view displays and what a determined caller can still reach.

In SQL Server, the solid pattern is to grant SELECT on the view and withhold permissions on the base tables. A report user then sees only the published columns, with names you've chosen. That reduces exposure, and it's why views belong in a data governance design. It doesn't, on its own, enforce which rows a specific user may infer.
Where the boundary leaks
A filter inside a view is not row-level security. If a user can still query a base table through another path, the view hides nothing. If a join changes how a predicate applies, restricted rows can leak through counts, error behavior, or timing differences even when the rows themselves never appear.
PostgreSQL makes this gap explicit. As PostgreSQL's CREATE VIEW documentation explains, ordinary views aren't physically materialized, security_barrier should be used when a view is intended to support row-level security, and security_invoker means querying users must have permissions on the underlying relations rather than relying on the view owner's rights. The planner can otherwise push predicates in ways that leak information about rows the caller shouldn't see.
Owner versus invoker execution changes your whole test plan. Under an owner-based path, access checks follow the view owner, so a broad owner can broaden access for everyone. Under an invoker path, each caller needs rights underneath, which is safer but breaks consumers you expected the view to shield from base table grants. Pick deliberately, and write the choice into the view header.
The walkthrough below reinforces how view permissions behave in practice before you run your own identity tests.
Run the identity matrix before go-live
Test four identities, not one happy path:
- Unauthorized user: Try a direct select, a join back to a base table, and an aggregate that could reveal a restricted customer count.
- BI identity: Confirm published columns work, then try to infer a hidden row through grouping and deliberate errors.
- Pipeline service account: Check it can't read columns the pipeline doesn't need, even though it runs unattended.
- Application identity: Compare query timing for existing and nonexistent restricted records, because a consistent timing gap is also disclosure.
Fail the view if any path reveals a restricted customer, salary, or order. Pair the view with row-level security or masking where the row itself is sensitive, audit who can ALTER the definition, and treat a view change as a security change. Creating the view can shrink exposure and still create false confidence if those identities aren't tested together.
Measure Read Gains Against Write Cost
An indexed view can reduce read work, but it adds work to every write that changes its underlying tables. That trade-off can turn a faster dashboard query into slower inserts, updates, and deletes. Test on production-shaped data and concurrency before adding the index.
SQL Server stores indexed-view results and maintains them as base-table data changes. The optimizer may use the indexed view, but whether it does depends on the query and SQL Server edition. Read the Microsoft guidance on indexed views and measure the trade rather than assuming the stored rows will improve every query.
The checklist below covers the evidence needed to decide whether the read gains justify the added write and storage costs.

Benchmark like production will hit it
Capture before-and-after results with production-shaped data and concurrency:
- Read latency: Record p50 and p95 to show typical and slower query response times.
- Read cost: Track CPU and logical reads for the queries consumers run.
- Storage growth: Measure the stored rows and indexes added to backups and maintenance.
- DML throughput: Compare completion rates for representative inserts, updates, and deletes.
Then check whether the production optimizer uses the index. Depending on SQL Server edition and query, NOEXPAND may be required. Confirm plan adoption using actual plans for consumer queries; a test plan alone doesn't prove production queries will use the indexed view. This matters in SQL Server data warehousing, where reporting reads and data loads share resources.
Eligibility rules that stop designs cold
An indexed view requires SCHEMABINDING, two-part object names, and deterministic expressions. Its first index must be unique and clustered, so the view's grain must identify each row uniquely. A GROUP BY view must include COUNT_BIG(*) and cannot use HAVING in its definition. Non-deterministic functions and certain join shapes, including outer joins, can make a view ineligible regardless of its benchmark results.
If reads don't improve enough to offset the write cost, drop the index. Keep the standard view and consider improving the base-table indexes instead.
A refreshable materialized view in systems that support it shifts the trade-off: stored results can reduce read work, while scheduled refresh introduces data lag and refresh cost. Set an acceptable freshness target, record the refresh schedule, and compare the resulting read gains with the storage and refresh effort. Keep the measurements with the deployment so future changes can show whether the optimization still pays for itself.
Fix the Errors That Block the View
Most view failures aren't mysterious. They're a short list of repeat offenders, and each one has a single change that fixes it without redesigning the view. Work through them in the order you'll meet them, from a basic CREATE rejection to indexed view eligibility.
Start with naming. An invalid or ambiguous column almost always means a join produced two columns with the same name and no stable alias. Qualify every selected column with its table alias and give every output a deliberate name. Don't let the engine guess, because its guess becomes your published contract.
Next, look at breakage after the fact. When a report breaks following a table change, the cause is usually **SELECT *** or positional column assumptions in the consumer. Replace the wildcard with named columns, redeploy, and rerun your reconciliation counts. The view's job is to absorb source change, and it can't do that if it passes every source change straight through.
Binding, indexing, and permission failures
SCHEMABINDING errors mean the binding clause is missing, names aren't two-part, or someone tried to alter a base object the bound view depends on. Add WITH SCHEMABINDING, qualify objects as schema.table, and change the base object only through a deployment that accounts for dependent views. Binding is friction on purpose. It stops a quiet table change from invalidating a contract downstream reports rely on.
Index rejections follow a strict order. If SQL Server refuses an index because the view lacks a unique clustered index, you either skipped that index or picked a key that isn't unique. Fix the key first, create the unique clustered index, and only then add nonclustered indexes. A GROUP BY view that's missing COUNT_BIG(*) or contains HAVING will also be rejected. Add the count, and move the having logic to an outer query over the view.
Permission failures look different. When the owner succeeds and the caller is denied, you're often seeing an owner versus invoker mismatch or a missing GRANT on the view while rights exist only on base tables. Grant SELECT on the view to the intended identity and retest as that identity, not as yourself. Testing as the owner proves the SQL parses. It proves nothing about access.
Finally, non-deterministic functions such as GETDATE() inside an indexed view definition fail eligibility. The stored rows can't depend on a value that changes without a write. Compute current date logic outside the view, in the consuming query or a parameter the caller supplies.
SQL view errors and the change that fixes them
| What you see | Usual cause | Change |
|---|---|---|
| Invalid or ambiguous column | Join output has no stable alias | Qualify and alias every selected column |
| Report breaks after a table change | SELECT * or positional columns | Name every column and reconcile counts |
| SCHEMABINDING error on create or alter | Binding omitted or base object changed | Add WITH SCHEMABINDING and two-part names |
| Index on view rejected | No unique clustered index, or key is not unique | Create that index first on a unique key |
| GROUP BY view rejected | Missing COUNT_BIG(*) or HAVING in the view | Add COUNT_BIG(*) and filter in an outer query |
| Caller denied, owner succeeds | Missing GRANT on the view while rights exist only on base tables | Grant SELECT on the view and retest each identity |
| Indexed view rejects GETDATE or similar | Non-deterministic expression | Move the function out of the view definition |
After each fix, rerun the row count and duplicate key checks. A repair that changes the grain while clearing the error message is worse than the error, because now the view deploys cleanly and reports wrong numbers.
Version the View and Decide the Next Step
A SQL view is a named contract, not a faster table. Version its output deliberately: consumers may depend on column names, types and grain, so a seemingly small definition change can break reports or alter their results.
Keep each view's script in the same repository as its tables. Record the grain, owner, classification and downstream reports in the file header. Before deployment, check dependency order so a base-table change does not leave the view invalid.
The minimum test pack
Run these checks on every change:
- Schema drift check: Fail the build if output columns, names or types change without an update to the versioned contract.
- Duplicate key check: Confirm the declared grain still holds. For open orders, that means one row per order key.
- Reconciliation total: Compare a trusted total with finance or the source system, and investigate unexplained movement.
- Permission retest: Test the consumer identities after any grant or view-definition change.
For SAP or operational sources landing in Azure or Databricks, keep the business SELECT stable and regenerate only the platform-specific wrapper. Kagool's Velocity is its proprietary SAP data ingestion accelerator. It automates the movement of SAP data to Azure and Databricks, so no separate SAP replication tool is needed. A stable ingestion contract helps keep platform-specific changes separate from the semantic layer, where views define the shape and meaning of data for consumers.
A view change is a contract change. Ship it with the same care as an API version update, because consumers can depend on its output in the same way.
Stay with scripts or escalate to a platform design
For one database and one team, a repository, tested grants and benchmarks may be enough. Extra platform process can add overhead without solving a real coordination problem.
A shared design becomes useful when views span SAP, Azure SQL, Fabric and Databricks, multiple identities consume the same definitions, and lineage is hard to produce. More one-off CREATE scripts will not resolve those coordination issues. A platform design can connect governed ingestion, a shared semantic layer and architecture decisions to enterprise data strategy. Kagool's data engineering as a service model supports Microsoft Azure, Microsoft Fabric and Databricks, and its Microsoft Fabric solutions connect architecture decisions with enterprise data strategy and requirements.
Use the number of platforms and consumer identity types as signals, not fixed thresholds. Once definitions cross team or platform boundaries, treat them as published data contracts. That means agreeing on ownership, change control and the tests consumers need before they rely on a view.
If views span SAP sources, Azure SQL, Fabric and Databricks, and grain, lineage or access are difficult to track, Kagool can discuss a design review for your view estate, refresh and security requirements, and platform architecture. Visit Kagool to talk through the options.

